

Publication Intelligence articles
The Impossible Third Index: How AI Changed Publication Intelligence
How a 1,104-page indexing assignment and seven versions of an automated editorial pipeline led to a subject index that outscored a professionally created published index.
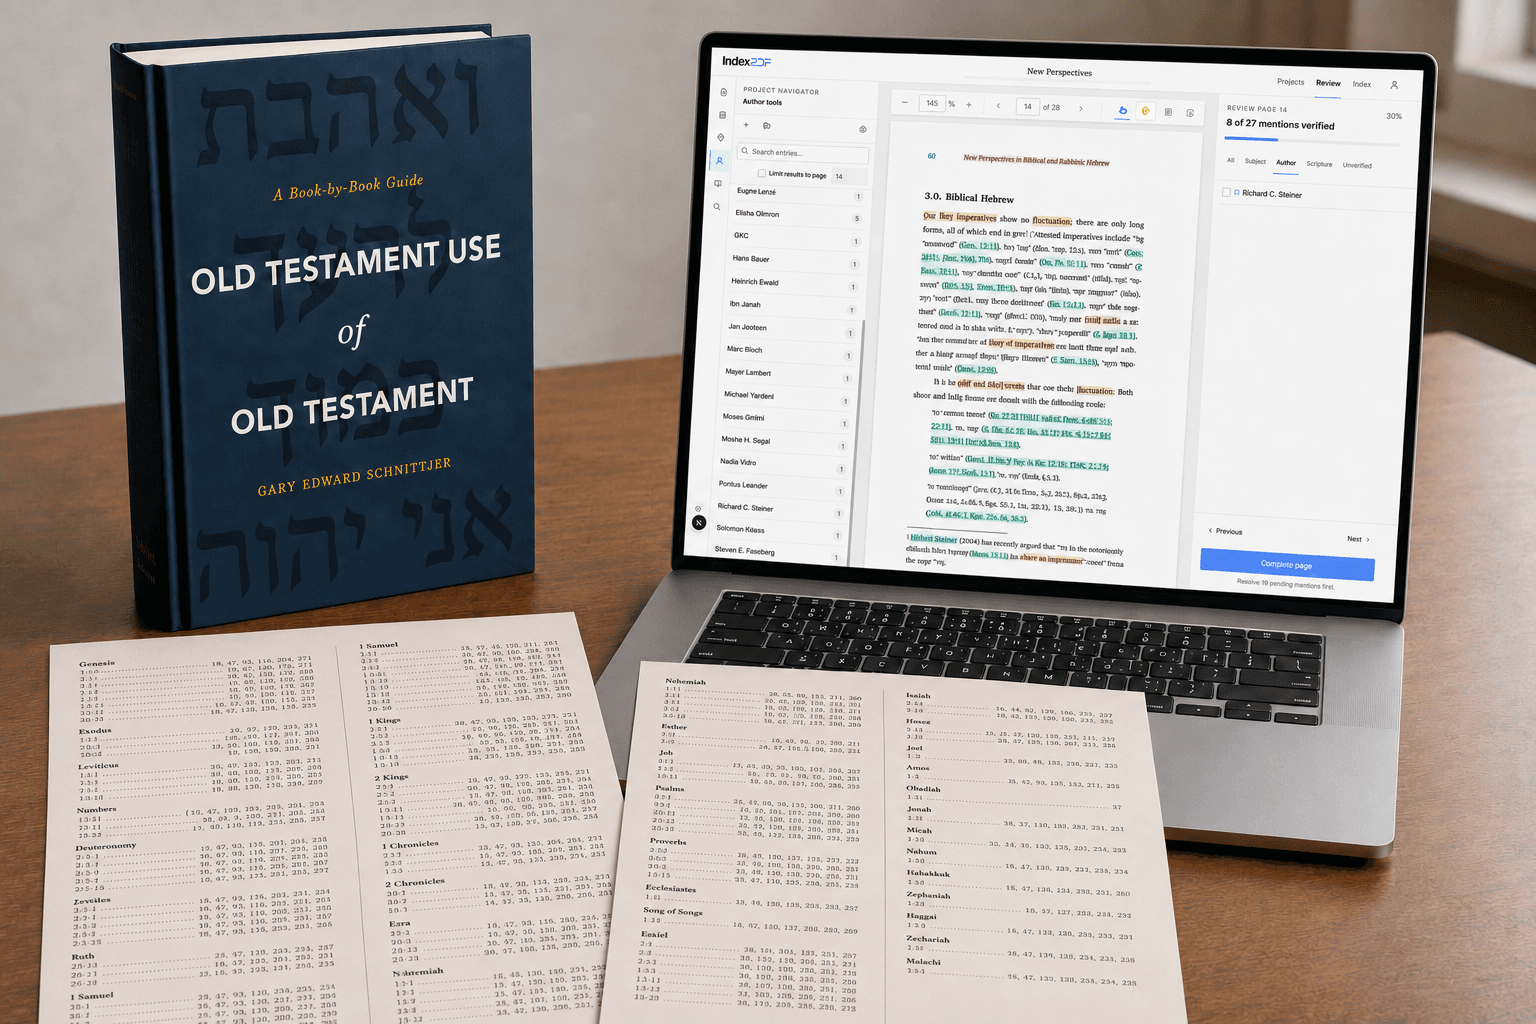
Djinndex began with three wishes: faster subject, author, and Scripture indexes. The third seemed beyond the reach of software. It no longer does.
On December 18, 2020, Zondervan sent me the final draft of the largest book I had ever agreed to index: Gary Edward Schnittjer’s Old Testament Use of Old Testament, a 1,104-page reference work about the Hebrew Bible’s reuse of its own texts. Its pages are dense with biblical citations, scholarly references, and tables. Its subject, author, and Scripture indexes would together occupy nearly 300 pages.
By then I had spent more than a year building software to help me finish it. My son was due in March. The index—and the software—were not yet done. He arrived first. My son was born on March 5, 2021. I delivered the indexes about a week later.
I developed the software against early versions of the manuscript as the book evolved. After the final draft arrived, I spent nearly three more months finishing the system, completing the largely hand-built subject index, and preparing the indexes for delivery. I later sent several rounds of corrections as I found things I wanted to improve.
Djinndex did not index an enormous book with the wave of a wand. It gave one person enough leverage to finish a project that might otherwise have taken months. It also taught me exactly where software stopped being useful.
Today, that project is Publication Intelligence. Its automated editorial pipeline can construct a complete subject index. It prepares the book, constructs and reconciles index material, edits the index as a whole, grounds locators in the source, and validates the result. In our published comparison, its unedited output outscored a professionally created published index.
The impossible third index has become possible. The harder question is what we should do with it.
Three wishes
Zondervan had recruited me for the Schnittjer project after I indexed the revised edition of John Goldingay’s Daniel in the Word Biblical Commentary series. While working on Daniel, I wrote shell scripts to find author names and Scripture references automatically.
For Schnittjer’s book, those experiments became Djinndex—a portmanteau of djinn and index. The name referred to three wishes: faster and better subject, author, and Scripture indexing.
Two of the wishes could be expressed as rules. I wrote parsers for the complicated ways Scripture references are written: abbreviations, chapter and verse ranges, discontinuous citations, and combinations of references. I wrote bibliography parsers that turned entries into structured data so the software could recognize an author in the many forms that might appear in the body or notes.
The other major advance was less glamorous and just as important: preparing the book’s text. A PDF does not necessarily contain sentences in the order a person sees them. Headers, footers, footnotes, multiple columns, and tables can turn an apparently orderly page into scrambled input. Schnittjer’s book contained complex, information-dense tables. Extracting them without destroying their meaning became part of the indexing problem.
This is still one of Publication Intelligence’s strengths. Before any parser or language model can interpret a book, the software has to recover the book that is actually on the page.
Djinndex became unusually capable on the book for which I built it. That was both its strength and its weakness. I tried to make the system general, but my first priority was finishing this particular assignment. It was a working tool, not yet a product. And my third wish remained stubbornly out of reach.
The index that was not in the text
Author and Source indexes begin with names and references printed in the book. Recognizing them still requires context, identity decisions, and an inclusion policy. A subject index adds another problem: identifying ideas that may never appear as an explicit label.
A subject index is not hidden inside a book waiting for the right parser. A passage may be about exile without using the word exile. A term may appear on fifty pages but deserve only three locators. Two passages may use different language for the same idea; two similar phrases may name importantly different ideas. The indexer must decide what matters, how it fits together, and what a future reader might call it.
A concordance tells you where a word appears. An index tells you where an idea matters.
I tried increasingly sophisticated ways to bridge that gap. At one point I built a vector database containing the roughly 1.8 million headings in FAST, the subject vocabulary derived from the Library of Congress Subject Headings. The system could associate passages with headings remarkably well; but the headings were still not enough.
The problem was not that 1.8 million possibilities constituted a small vocabulary. It was that the possible subjects of books are effectively unbounded. Back-of-book indexes routinely require distinctions more specialized than a vocabulary designed to organize entire libraries. A universal list could tell me what a passage resembled. It could not decide what this particular book was trying to say.
My third wish required interpretation, and I came to believe that software could not grant it.
The detour that was not a detour
By the time I delivered the indexes, I had spent seven years in graduate school and become a PhD candidate in Old Testament at Fuller Theological Seminary. I also had substantial student debt and a newborn son. During the year I built Djinndex, software engineering had steadily displaced my doctoral work. After my son was born, it became hard to regard that displacement as a hobby.
I applied for software jobs and was hired by Box. For the next four and a half years, I worked on web applications, testing, and product interfaces used at enormous scale.
I thought of the work as preparation. Djinndex had shown me that the idea was valuable, but also how far a tool made for one person and one book was from a product others could trust. A real indexing system would have to survive irregular documents, expose its evidence, make thousands of small decisions manageable, and help users find errors the system itself could not recognize.
By the time I was ready to return, software engineering was undergoing its own upheaval. Technological change is usually described from a distance. A new capability appears, a productivity curve rises, and “workers” move from one category to another. From inside a life, those categories are years: skills acquired, debts incurred, identities assembled, and plans made for people one loves.
I had already watched social change reshape the academic world in which I trained. Then AI began reshaping software engineering. Now it was bringing me back to indexing—but to a form of indexing very different from the one I had left.
That history makes me reluctant either to minimize what AI can do or to celebrate disruption carelessly. The capability is real, but so are the consequences for us “workers.”
Then the threshold moved
The result that changed my mind did not come from Publication Intelligence. I encountered IndexerLabs and spent an entire weekend testing and analyzing its subject-indexing capabilities, increasingly astonished by what I found. The indexes had weaknesses, but they approached professional quality. They bore the shape of editorial judgment: selecting, consolidating, and organizing ideas in ways I had believed software could not.
At first, I assumed that matching IndexerLabs would require specialized training on a large collection of professional indexes. Experiments with frontier general-purpose models showed that specialized training was not the missing ingredient. The models supplied capabilities I could build on, but turning those capabilities into a strong finished index required a carefully engineered system.
Let me qualify that claim by pointing out that one excellent result does not establish reliability across every genre, length, and editorial standard. The American Society for Indexing’s 2026 trajectory report remains skeptical of LLM-generated indexes, which can appear convincing while concealing serious omissions and structural failures.
The result changed my understanding of the task. The system can perform the selection, interpretation, organization, and editorial refinement that I once believed had to remain human work. The evidence is the quality of the resulting index, not merely its resemblance to one.
A generated answer is not a publishing process.
Seven versions to cross the threshold
Reaching this level took seven versions of the indexing pipeline, extensive experimentation, and many refinements within the current version. We tested different ways to extract and organize the book, construct entries, reconcile concepts, edit the complete index, and verify its references. This was a sustained engineering effort.
The current pipeline has many computationally expensive, time-consuming stages. It spends that work on decisions a single prompt leaves unfinished: book-wide coverage, concept relationships, useful access paths, whole-index editing, and source-grounded locators. A general-purpose language model does not deliver this result out of the box.
In our source-grounded comparison for The Oxford History of the French Revolution, Publication Intelligence scored 98.05 out of 100, compared with 88.43 for the professionally created published index. Our generated index was evaluated as delivered, without subsequent human editing. Read the comparison and its evaluation basis.
A prompt is not a publishing process
You can give a powerful language model a book and ask for an index. The answer may be impressive. But a single response has not recovered the real structure of the final PDF, kept the whole book in view, reconciled repeated ideas, checked the finished hierarchy, or shown why each locator belongs.
Publication Intelligence treats those responsibilities as a long-running editorial process. It first prepares the final PDF and recovers its document structure. It constructs index material across the book, reconciles the pieces, audits and edits the complete subject index, grounds retained locators in exact source evidence, and validates the result. Project-specific estimates show that this work continues in the background rather than pretending that a finished index appears immediately.
- Prepare the final PDF and recover the book’s readable structure.
- Construct and reconcile index material across the publication.
- Audit and edit the complete subject index.
- Organize headings, subdivisions, terminology, and cross-references.
- Ground locators in exact source evidence.
- Validate the result and surface unresolved questions for review.
The handoff is an index with source evidence and book-wide editorial work already completed. Review tools let users inspect the result, investigate uncertainty, and tailor it to a publication. That option does not mean a professional indexer must finish the intellectual work the system has already performed.
The index is edited before you see it
Subject-index quality depends on relationships that are visible only when the index is read as a whole. A useful heading can be weak because its subheadings repeat one another. Two sensible entries can provide redundant access. A cross-reference can send the reader through an unnecessary detour. Several locally plausible terms can conceal one inconsistent vocabulary.
Publication Intelligence performs a whole-index editorial pass before handoff. It can consolidate fragmented access without erasing real distinctions, improve heading and subheading organization, reconcile terminology and style, remove unnecessary cross-reference detours, and preserve alternate access that helps a reader. The aim is not merely to accumulate correct-looking entries. It is to edit the subject index as a navigation system.
Because retained locators remain connected to exact passages, unresolved grounding or organization questions can be surfaced instead of silently accepted. That evidence-grounded relationship is also what makes the later verification workflow inspectable.
Choose the review depth
For projects where you want additional inspection or editorial changes, the workspace offers two review strategies:
- Priority review focuses on detected blockers and unresolved subject-heading issues. Clearing that queue does not establish that omissions or unflagged errors are absent, and it does not complete Full review.
- Full review covers every eligible page and every generated mention, including pages where no mention was found. It is exhaustive in workflow scope, not a guarantee that human error or every publication-specific issue is impossible.
A reviewer can switch between Priority and Full review without losing earlier decisions or full-review progress. The choice changes the inspection path, not the underlying index.
The author and the map
Authors, editors, and professional indexers bring different knowledge to the review.
Professional indexers understand access paths, reader behavior, index structure, and the constraints of a publisher’s style. But the author knows the territory. The author knows which distinction is foundational, which phrase is merely incidental, whether two terms name the same idea, and where an argument matters even though it is never announced.
An author may want to emphasize a particular argument. An indexer may refine access paths or house style. A publisher sets the required scope and production form. The finished automated index gives each of them something concrete to inspect and adapt.
The new division of labor is simple:
- Publication Intelligence constructs, reconciles, edits, grounds, and validates the index.
- The workspace keeps the index connected to the passages behind it.
- Authors, editors, and indexers can inspect evidence, resolve project-specific questions, and tailor the result when needed.
Professional indexers can contribute specialist expertise, house-style refinement, and independent quality assurance. Authors and publishers can choose that help for the needs of a particular book. Our comparison shows that the automated index can already exceed a professionally created published index without subsequent human editing.
Export and handoff
The final workspace keeps headings, subheadings, locators, groups, and cross-references together. Cross-reference destinations are navigable, so a reviewer can inspect the route a reader will follow before export.
The index workspace offers exports in Markdown, JSON, and editable Word (.docx). A standalone Word index is a production handoff: it does not embed index markers in the source manuscript or automatically update locators after repagination. Agree the publisher’s required format and check final style and proofs. See current pricing and the workflow for publishers.
Publication choices and optional review
A publication may have particular requirements for scope, terminology, house style, and production format. The workspace lets users adapt the index to those requirements and investigate any questions they want to examine. Source evidence supports inspection of existing entries; reading from the source toward the index can also help investigate possible omissions.
Publication approval, typesetting, and final proofreading are production decisions. They are distinct from the claim that an index needs human editorial reconstruction to reach professional quality. Our measured result demonstrates that the automated pipeline can reach and exceed that level before a person edits its output.
When I began Djinndex, I tried to grant myself three wishes through parsers, regular expressions, and a great deal of stubbornness. The third wish became possible through seven versions of an editorial pipeline, extensive experimentation, and many refinements to the current version. Language models made the work possible; the system built around them made the result good enough to outperform the published human-created index in our comparison.
Sources and further reading
- Dennis Duncan, Index, A History of the: A Bookish Adventure from Medieval Manuscripts to the Digital Age, on the index as information technology, argument, and literary form.
- OCLC, FAST (Faceted Application of Subject Terminology), on the approximately 1.8 million-heading vocabulary derived from Library of Congress Subject Headings.
- American Society for Indexing, AI and Book Indexing: Trajectory Data (2026), a skeptical empirical assessment of LLM-generated indexes.